Independent local AI benchmark
Can a small firm use AI on confidential work without sending it to an AI provider?
We tested a EUR 3,680, 128 GB mini-PC on the document and meeting work solicitors, accountants, and advisers handle every day. The short answer is yes, within a clearly defined range of work - and professional review stays in the loop.
Page updated 2026-09-22
Read the short answer Inspect the evidence
Release 4.6 - benchmarking runs 3-17 July 2026; data frozen 2026-07-17. This page is the conclusion. Every figure carries its source, and the Evidence page holds the method, the corrections, and the raw files.
The short answer
We tested a small 128 GB AI computer on the kind of document and meeting work handled by solicitors, accountants, and other professional firms.
The short answer is yes, within a clearly defined range of work.
A machine like this can read and summarise documents, extract information, prepare first drafts, transcribe meetings, and create files while processing the material locally. For routine work based on documents you already have, the results were strong enough to be genuinely useful.
It is not a private replacement for the best cloud AI. It is less capable on difficult reasoning and open-ended drafting, and important work still needs professional review.
That leads to a fairly simple conclusion:
Local AI makes sense when confidentiality is stopping useful work from being done with AI. It makes much less sense if your main objective is simply to reduce your AI bill.
If that is all you needed, you can stop here. The rest of this page is the reasoning behind it, and the limits.
What we tested
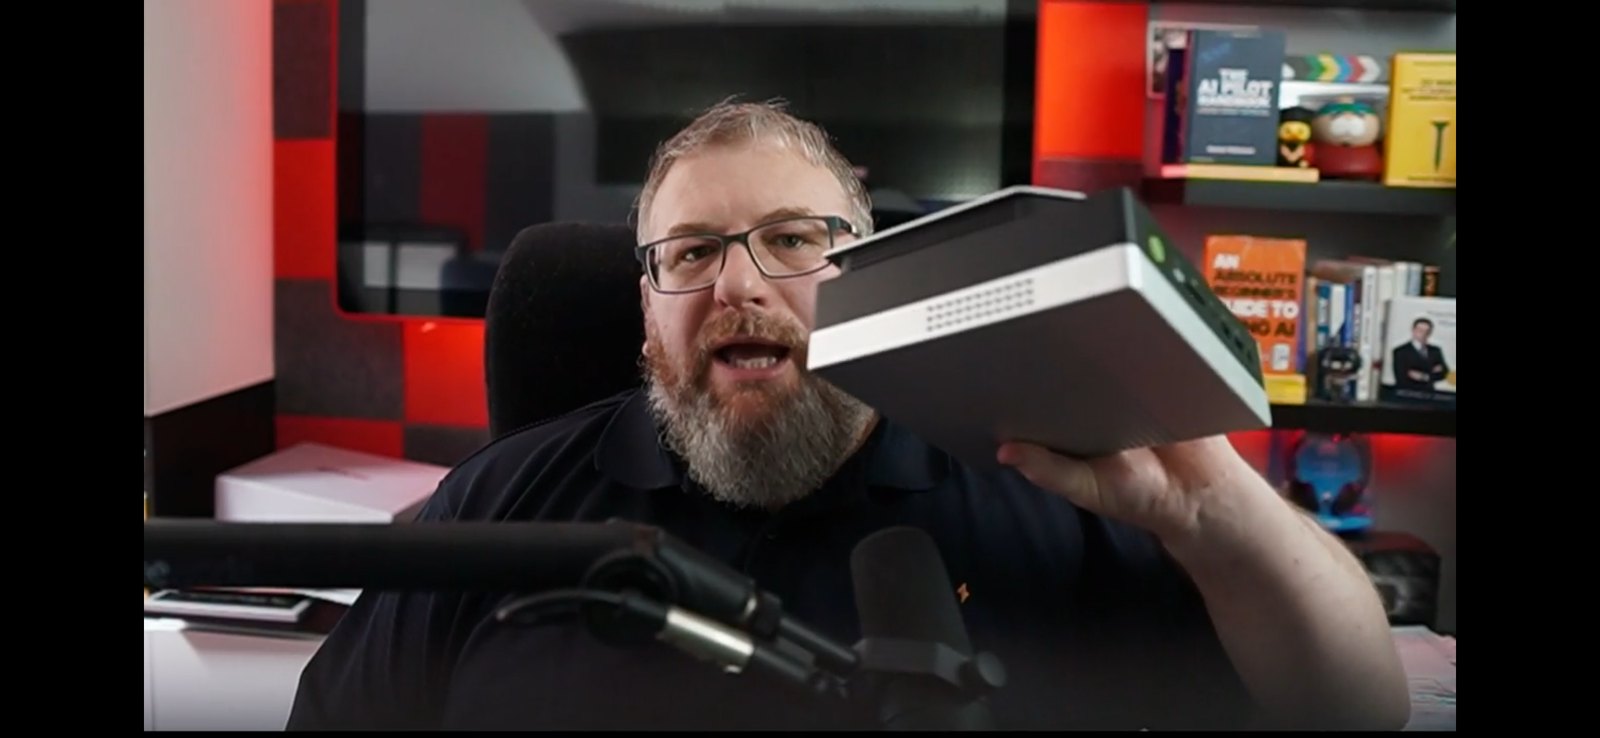
The test machine was a GMKtec EVO-X2 with an AMD Ryzen AI Max+ 395 processor and 128 GB of unified memory.
It cost approximately EUR 2,960 before Irish import VAT, or about EUR 3,680 including it.
We tested it on document reading, summarisation, structured extraction, drafting, office-tool use, long documents, meeting transcription, speaker identification, image generation, and speech generation.
We also deliberately pushed it beyond the workloads we would normally recommend, so that we could find the boundaries rather than only demonstrate the successes.
What would this actually do in a small firm?
Imagine a solicitor uploads a lease and asks:
"What is the term, when can either party terminate, what notice is required, and are there any unusual obligations I should look at?"
That is the kind of task local AI is good at.
The source document is in front of the model. Its job is to find, organise, and explain information that is already there.
The same applies to summarising a long agreement, extracting dates and amounts, turning meeting notes into an attendance note, triaging a set of documents, or preparing the first draft of routine correspondence.
The machine is much less convincing when the task becomes:
"Here are some incomplete facts. Work out the best legal or commercial strategy."
That requires more independent judgement and reasoning. The strongest cloud models remain better suited to that kind of work.
So the useful dividing line is not simply local versus cloud. It is this:
Use local AI for confidential, routine, and document-grounded work. Keep harder judgement with a person, or use a stronger cloud model where the material is suitable for cloud processing.
How good is the output?
There are two different answers, and keeping them separate is important.
On a controlled document-summarisation test, the everyday local model passed 28 of 30 checks. That tells us it is good at finding and working with facts in supplied material.
But when we tested realistic professional drafts and asked whether they were close to something a professional could send or file, the best local results were around 3 out of 5 - the middle of the scale. They were useful drafts, but they still needed a real edit.
Those findings are not contradictory. The machine can be good at the facts while still producing prose that needs work.
That is how I would set expectations inside a firm: use it to remove blank-page work and speed up reading, extraction, and first drafting. Do not remove the professional from the final decision.
Where local AI is strongest
The strongest use cases in our testing were tasks where the machine had a clear source of truth.
- Document extraction worked well.
- Document summarisation worked well.
- Questions about supplied documents worked well.
- Meeting transcription was extremely fast: approximately one hour of audio in two minutes.
- Routine categorisation and triage were fast enough to run continuously or in batches.
The common feature is that the model is being asked to process information, rather than to invent expertise it has not been given.
Drafting is useful, but different
Local drafting is useful as a first-draft engine.
It can prepare a client email, letter, attendance note, or clause in seconds. But our tests consistently found a gap between producing a plausible draft and producing something a professional would send with only light edits.
We tried several obvious ways of closing that gap: much larger models, reasoning models, self-critique, better examples, and combinations of several models. None removed it.
That is an important result because it saves a buyer chasing the wrong solution.
You do not need a 120-billion-parameter model to write routine correspondence. You need a good everyday model, a sensible workflow, and a person who remains responsible for the final output.
Can it learn the firm's writing style?
Yes, within limits.
We trained a model on the box itself to reproduce a particular house style. The training and subsequent use ran entirely on the box, with no cloud step.
The model became noticeably better at tone and register.
What did not improve materially was the amount of professional editing the document needed.
So fine-tuning is useful if the goal is "make our first drafts sound like us". It is not a way of achieving "make review unnecessary".
Can it actually do things, rather than just write text?
Yes.
We gave the model ordinary office tools such as creating a Word document, looking up information, adding a reminder, and sending a message.
The recommended general-purpose model selected the correct tool about 91% of the time in the test suite, and produced no malformed tool calls.
That makes practical integrations realistic.
But another result matters just as much. When the model had to apply a judgement inside the action - for example, mark something urgent only if a particular condition was true - several models applied the action whether the condition was true or not.
That suggests a useful design rule:
Let software rules or people make important decisions. Let the AI perform the mechanical work once the decision has been made.
Creating the document is a good AI task. Deciding whether the document carries a high-risk legal consequence needs a stronger control.
Whether a model drives your document tools also depends on how it is served, not only on which model you chose: one capable model would not use tools at all until it was configured correctly. Test it on your own stack. The setup detail is on the In Practice page.
Meetings may be one of the strongest use cases
The box transcribed one hour of audio in roughly two minutes.
We also tested some less obvious failure modes.
Speech-recognition models can invent words during silence. In our tests, enabling proper voice-activity detection removed that problem completely across the silence conditions we tested.
Separating every speaker in a busy meeting remained difficult. A specialist system still performed better.
But we found that the more useful business question was often simpler: was this me speaking, or somebody else?
Using a short voice sample from the host, the system labelled 97.2% of transcript lines correctly as host-versus-other across four real calls.
That is not proof of perfect meeting diarisation. It shows something more practical: a useful meeting system can sometimes be built by solving the narrower business problem instead of trying to solve the hardest technical version of it.
Is it fast enough?
For normal work, yes.
A short email or extraction task can complete in a few seconds.
A substantial document may take tens of seconds to a few minutes before the first answer.
Meeting transcription runs much faster than real time.
Very long documents remain readable by the system, but there comes a point where waiting several minutes for the first answer stops feeling conversational. At that point the workload is better treated as a background or overnight job.
So I would describe the machine as fast for everyday office work, patient rather than instant on very large documents.
How many people can use one box?
One box is a sensible starting point for a small team of three to five people whose use is intermittent.
One person gets the full performance of the machine. If several people ask substantial questions at exactly the same time, they share that capacity.
For a four-person professional practice where people make occasional requests throughout the day, that is quite different from four people continuously generating AI work.
The first scenario fits this machine well. The second eventually needs more capacity.
Think of it as a shared office appliance, not a miniature data centre.
What does "local" really buy you?
The main benefit is not cheaper tokens.
It is that, in the configuration we tested, the documents and prompts being processed by the AI model did not need to be sent to an external AI provider.
That can make an important class of confidential work possible with AI when a firm would otherwise decide not to use an AI service at all.
There is an equally important qualification.
Running AI locally does not automatically make the system secure or compliant. The machine still needs normal professional IT controls: user access, encryption, patching, backups, logs, and appropriate policies.
Local processing changes who receives the data. It does not remove the need to look after the data.
Will it save money?
Probably not, if that is the only reason you are buying it.
At the workload we modelled - roughly 5,000 document tasks per year - cloud AI was inexpensive enough that the local machine did not beat the cheaper cloud options on total cost: about EUR 3,700 over three years against roughly EUR 85.
The hardware dominates the local cost.
Once you own the machine, however, another thousand local tasks cost almost nothing beyond electricity.
| Three-year cost (~5,000 doc tasks/yr) | Total |
|---|---|
| Local machine (hardware-dominated) | ~EUR 3,700 |
| Cheap EU cloud | ~EUR 85 |
| Frontier cloud | ~EUR 907 |
So there are cases where high volume matters: on running cost alone the machine pays back against the frontier tier above about eighty tasks a day. But for an ordinary small professional firm, I would not build the business case around token savings.
The stronger case is: we have work that would benefit from AI, but we do not want that material sent to an external model provider. If that problem is worth solving, the economics look very different.
Where it does not fit
This is not the right answer if most of your AI use is occasional and non-confidential.
It is not the right answer if you need frontier-level reasoning on almost every request.
It is not the right answer for a large group of people continuously using heavy AI workloads at the same time.
And it is not yet a consumer appliance that you take out of the box and hand to staff without technical setup.
There is another practical limit worth understanding. We deliberately tested extremely large models close to the machine's memory limit and found conditions that could lock the machine hard enough to require a power cycle.
Those are not the models we recommend for normal document work.
The everyday models stayed well away from that boundary. The lesson is not "the box is unstable". It is that there is little business reason to operate it at the engineering limit merely because you can.
So should a small firm buy one?
I would not start with the purchase. I would start with the work.
Find three or four confidential workflows that people already perform regularly: reviewing agreements, extracting information, summarising files, preparing routine correspondence, transcribing meetings.
Then run a pilot using real examples, and measure two things:
- How much time did the AI save before review?
- How much review did the output require?
If the saving survives the review step, and confidentiality is materially easier because processing stays local, you have a business case.
If it does not, the fact that the machine can run a large language model is irrelevant.
That is the result I take from this research. Local AI is now practical enough to deserve serious consideration in small professional firms. But the reason to adopt it is not that it replaces professional judgement. It is that it can privately remove a substantial amount of routine work that surrounds that judgement.
Not sure which of your workflows suit local AI? The quickest way to find your best candidates is to score them. Our RATES framework walks you through rating your everyday tasks so the strongest opportunities rise to the top. If you would rather talk it through, you can book a Focus Call and we will pressure-test your shortlist and map a realistic first project.
Want to check the work?
This page is the conclusion rather than the laboratory notebook.
The In Practice page explains the deployment we would actually use.
The Evidence page contains the test methods, corrections, raw findings, and provenance behind the claims above.
The complete data package is also available for anyone who wants to reproduce or challenge the results.
Pushing the box to its limits is the research notebook: what happened when we deliberately ran models far larger than the ones recommended here. It is laboratory work, not buying advice.
This page shows that a machine like this can do real work. The harder question - what to adopt, in what order, and how to bring your team with you - rarely starts with a hardware decision at all. That is the work we do with organisations, at the adoption layer: helping decide which confidential workflows belong on a local machine, which are better left in the cloud, and what a first pilot should test. We do not sell or install the hardware - we help you use it well.
Glossary
- Large language model (LLM)
- the kind of AI that reads and writes text - the technology behind ChatGPT and the local models here.
- Local / on-premises
- running on a computer you own, on your own network, rather than on a company's servers over the internet.
- Frontier model
- the largest, most capable cloud AI systems.
- Token
- roughly a word-piece; AI speed and document length are measured in tokens (about three-quarters of a word each).
- Send-readiness
- our one-to-five measure of whether a professional would send or file a draft with only light edits - distinct from factual accuracy.
- Faithfulness
- whether the output sticks to the facts in the source and invents nothing.
- Fine-tune / LoRA
- training an existing model on your own examples so it adopts your style; a LoRA is a small, efficient way to do this that runs on this hardware.
- llama.cpp / llama-server
- the open-source software that runs the models and serves them over a normal web API on your network.
- Voice-activity detection (VAD)
- software that identifies which parts of a recording contain speech, so the transcriber does not try to transcribe silence.
© 2026 Alastair McDermott / HumanSpark AI - CC BY 4.0. Reuse freely with attribution and a link to humanspark.ai. Release 4.6; benchmarking runs 3-17 July 2026, data frozen 2026-07-17.
Written by Claude Code, working with Alastair McDermott. How this was made →